-
Google Cloud Dataflow is a fully-managed cloud service and programming model for batch and streaming big data processing.
- Scalability - Google Cloud Dataflow can automatically scale up or down depending on your data processing needs, handling massive datasets with ease.
- Fully Managed - Dataflow is a fully managed service, which means you don't have to worry about managing the underlying infrastructure.
- Unified Programming Model - It provides a single programming model for both batch and streaming data processing using Apache Beam, simplifying the development process.
- Integration - Seamlessly integrates with other Google Cloud services like BigQuery, Cloud Storage, and Bigtable.
- Real-time Analytics - Supports real-time data processing, enabling quicker insights and facilitating faster decision-making.
#Data Dashboard #Big Data #Data Management 14 social mentions
-
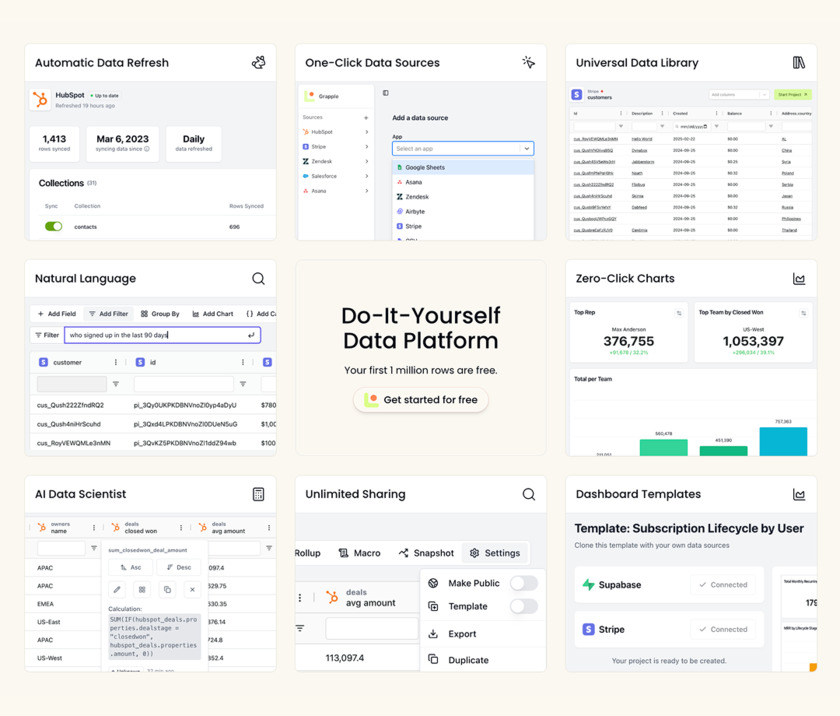
Do-It-Yourself Data Analytics & Business Intelligence, Powered by AIPricing:
- Freemium
- $99 / Monthly (Per Editor, Unlimited Viewers)
- Universal Data Library - Automatic data modeling ensures your data is clean and queryable
- Map Data - Combine, merge, and map data from across disparate sources for a full picture of your business.
- Automatic Data Refresh - Hourly data refresh from your favorite apps like Salesforce, Hubspot, Zendesk, Stripe, and more!
- Natural Language - Filter, visualize, and calculate with just your words—no SQL required.
- AI Data Scientist - Create custom calculations and aggregations across multiple sources without writing any SQL or formulas
#Data Dashboard #Data Visualization #Data Analysis Featured
-
Apache Spark is an engine for big data processing, with built-in modules for streaming, SQL, machine learning and graph processing.Pricing:
- Open Source
- Speed - Apache Spark processes data in-memory, significantly increasing the processing speed of data tasks compared to traditional disk-based engines.
- Ease of Use - Spark offers high-level APIs in Java, Scala, Python, and R, making it accessible to a broad range of developers and data scientists.
- Advanced Analytics - Spark supports advanced analytics, including machine learning, graph processing, and real-time streaming, which can be executed in the same application.
- Scalability - Spark can handle both small- and large-scale data processing tasks, scaling seamlessly from a single machine to thousands of servers.
- Support for Various Data Sources - Spark can integrate with a wide variety of data sources, including HDFS, Apache HBase, Apache Hive, Cassandra, and many others.
#Big Data #Databases #Big Data Infrastructure 80 social mentions
-
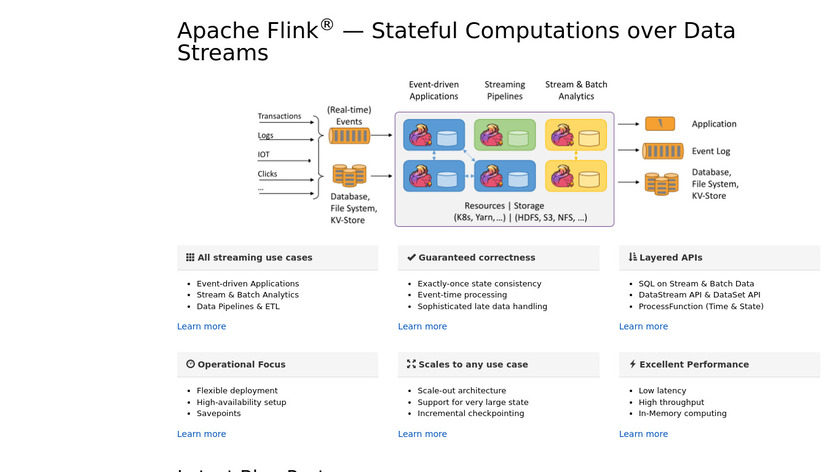
Flink is a streaming dataflow engine that provides data distribution, communication, and fault tolerance for distributed computations.Pricing:
- Open Source
- Real-time Stream Processing - Apache Flink is designed for real-time data streaming, offering low-latency processing capabilities that are essential for applications requiring immediate data insights.
- Event Time Processing - Flink supports event time processing, which allows it to handle out-of-order events effectively and provide accurate results based on the time events actually occurred rather than when they were processed.
- State Management - Flink provides robust state management features, making it easier to maintain and query state across distributed nodes, which is crucial for managing long-running applications.
- Fault Tolerance - The framework includes built-in mechanisms for fault tolerance, such as consistent checkpoints and savepoints, ensuring high reliability and data consistency even in the case of failures.
- Scalability - Apache Flink is highly scalable, capable of handling both batch and stream processing workloads across a distributed cluster, making it suitable for large-scale data processing tasks.
#Big Data #Stream Processing #Web Frameworks 47 social mentions
-
Apache Kafka is an open-source message broker project developed by the Apache Software Foundation written in Scala.Pricing:
- Open Source
- High Throughput - Kafka is capable of handling thousands of messages per second due to its distributed architecture, making it suitable for applications that require high throughput.
- Scalability - Kafka can easily scale horizontally by adding more brokers to a cluster, making it highly scalable to serve increased loads.
- Fault Tolerance - Kafka has built-in replication, ensuring that data is replicated across multiple brokers, providing fault tolerance and high availability.
- Durability - Kafka ensures data durability by writing data to disk, which can be replicated to other nodes, ensuring data is not lost even if a broker fails.
- Real-time Processing - Kafka supports real-time data streaming, enabling applications to process and react to data as it arrives.
#Data Integration #Monitoring Tools #Stream Processing 160 social mentions
-
Amazon Kinesis services make it easy to work with real-time streaming data in the AWS cloud.
- Real-time data processing - Amazon Kinesis allows for real-time processing of data streams, enabling rapid ingestion and analysis of data as it arrives.
- Scalability - Kinesis is highly scalable and can handle massive volumes of streaming data, expanding automatically to meet your needs.
- Fully managed service - As a fully managed service, Kinesis handles infrastructure maintenance, provisioning, and scaling, reducing operational overhead.
- Integration with AWS ecosystem - Kinesis integrates seamlessly with other AWS services such as Lambda, Redshift, S3, and Elasticsearch, facilitating comprehensive data workflows.
- Multiple data stream applications - The service supports different types of data stream applications including data delivery, analytics, and real-time processing, making it versatile.
#Big Data #Data Management #Stream Processing 28 social mentions
-
DuckDB is an in-process SQL OLAP database management systemPricing:
- Open Source
- Lightweight - DuckDB is a lightweight database that is easy to install and use without requiring a separate server process.
- In-Memory Processing - It supports efficient in-memory execution, which makes it suitable for analytical queries that require quick data processing.
- Columnar Storage - DuckDB uses a columnar storage format that optimizes for analytical workloads by improving read performance for large datasets.
- Integration with Data Science Tools - The database integrates well with popular data science tools and libraries such as Pandas, R, and Jupyter Notebooks.
- SQL Support - DuckDB offers full support for SQL, allowing users to leverage their existing SQL knowledge without having to learn new query languages.
#Big Data #Databases #Data Integration 48 social mentions
-
Open-source software for reliable, scalable, distributed computingPricing:
- Open Source
- Scalability - Hadoop can easily scale from a single server to thousands of machines, each offering local computation and storage.
- Cost-Effective - It utilizes a distributed infrastructure, allowing you to use low-cost commodity hardware to store and process large datasets.
- Fault Tolerance - Hadoop automatically maintains multiple copies of all data and can automatically recover data on failure of nodes, ensuring high availability.
- Flexibility - It can process a wide variety of structured and unstructured data, including logs, images, audio, video, and more.
- Parallel Processing - Hadoop's MapReduce framework enables the parallel processing of large datasets across a distributed cluster.
#Big Data #Databases #NoSQL Databases 29 social mentions
-
Apache Beam provides an advanced unified programming model to implement batch and streaming data processing jobs.Pricing:
- Open Source
- Unified Model - Apache Beam provides a unified programming model that simplifies the development of both batch and stream processing applications. This reduces the complexity in maintaining separate codebases for different types of data processing needs.
- Portability - The portability of Apache Beam allows developers to write their code once and run it on different execution engines like Apache Flink, Apache Spark, and Google Cloud Dataflow, offering flexibility in choosing the right runtime environment.
- Rich SDKs - Apache Beam offers rich SDKs for multiple languages including Java, Python, and Go, allowing a broader range of developers to leverage its capabilities without being restricted to a single programming language.
- Windowing and Triggering - It provides powerful abstractions for windowing and triggering, enabling developers to handle out-of-order data and late data arrivals efficiently, which is crucial for accurate stream processing.
#Data Dashboard #Big Data #Big Data Tools 16 social mentions
-
Managed Apache Spark and Apache Hadoop service which is fast, easy to use, and low cost
- Managed Service - Google Cloud Dataproc is a fully managed service, which reduces the complexity of deploying, managing, and scaling big data clusters like Hadoop and Spark.
- Integration with Google Cloud - Seamlessly integrates with other Google Cloud services like Google Cloud Storage, BigQuery, and Google Cloud Pub/Sub, allowing for easy data handling and processing.
- Scalability - Can quickly scale resources up or down to meet the computing demands, making it flexible for different workload sizes and types.
- Cost Efficiency - Offers a pay-as-you-go pricing model, and can utilize preemptible VMs for reduced costs, making it a cost-effective option for running big data workloads.
- Customizability - Supports custom image management and initialization actions, allowing users to tailor clusters to meet specific needs.
#Data Dashboard #Big Data #Big Data Tools 3 social mentions
-
DaytaBrain is your AI strategy partner: it keeps strategy and execution connected, warns leaders when initiatives drift, recommends the next decision and learns from the results. The 20 to 60 hours per cycle spent on reports? Gone.Pricing:
- Paid
- Free Trial
- Plan vs. Reality - Ties every initiative to the goals, KPIs and assumptions it was approved on, and shows where results are pulling away from the plan.
- Assumption Alerts - Shows which assumption behind a plan has broken, not just that a number turned red.
- Pre-Review Warnings - Emails each owner before their review to flag out-of-date data, slipping KPIs and work behind schedule.
- Decision Recommendations - When an initiative drifts, explains why and recommends what leaders should decide next. People always make the call.
- Decision Tracking - Tracks whether past decisions moved their KPIs, compares acting now with deferring, and reminds you to check in at 30, 60 and 90 days.
#Program Management #Strategy Management #Productivity Featured
Top 9 Big Data in Stream Processing
The best Big Data within the Stream Processing category - based on our collection of reviews & verified products.
Sponsored products